Illa’s source
Original draft, image, video, post, or manuscript page. Preserve the file, URL, available metadata, and the date Illa says it was created or published.
The interview describes a long-running relationship with AI and several places where Illa believes her words or images reappear. The materials currently available do not include an archive of her websites, dated original posts, platform notices, or source-to-match pairs. This page makes that gap visible so it can be filled carefully.
Illa says she wrote a handwritten book in 2016. She describes later versions, including versions developed with AI assistance. The original manuscript and version history have not yet been examined for this project.
In the November 9, 2026 interview, Illa said she had spent about 15 hours a day using AI technologies for the preceding two years. She describes repeated prompting, correction, and response as a bidirectional learning loop. Account logs or usage records were not supplied.
Illa reports having a timestamp from April 2025 for work on her predictive-analytics and feedback-loop ideas. A timestamp may help establish that a file existed by a date; its meaning depends on the underlying record. The timestamp, application materials, and any patent filing receipt have not been reviewed here.
Illa describes seeing familiar words, names, images, and themes in YouTube videos, Facebook, Reddit, X/Twitter, Quora, and AI responses. She also says that she was moving files after suspecting unauthorized access. These are reports made in the interview; the specific posts, dates, account records, and technical evidence needed to verify them were not attached.
The presentation is an invitation to refine the research questions, source ledger, and experimental design with scholars and practitioners. See the session page for participation details.
At present, the interview names platforms and describes perceived matches, but it does not provide a complete list of Illa’s former or current websites, direct links to the posts in question, or official notices documenting removal. So this page does not state that a platform took down a particular site or caused a particular loss.
For each website, account, or post, the archive should record its URL, account holder, first known date, last known date, original files, public status, and any contemporaneous platform communication. If a page is unavailable, record the exact URL and date checked; “not found” is an observation, not an explanation.
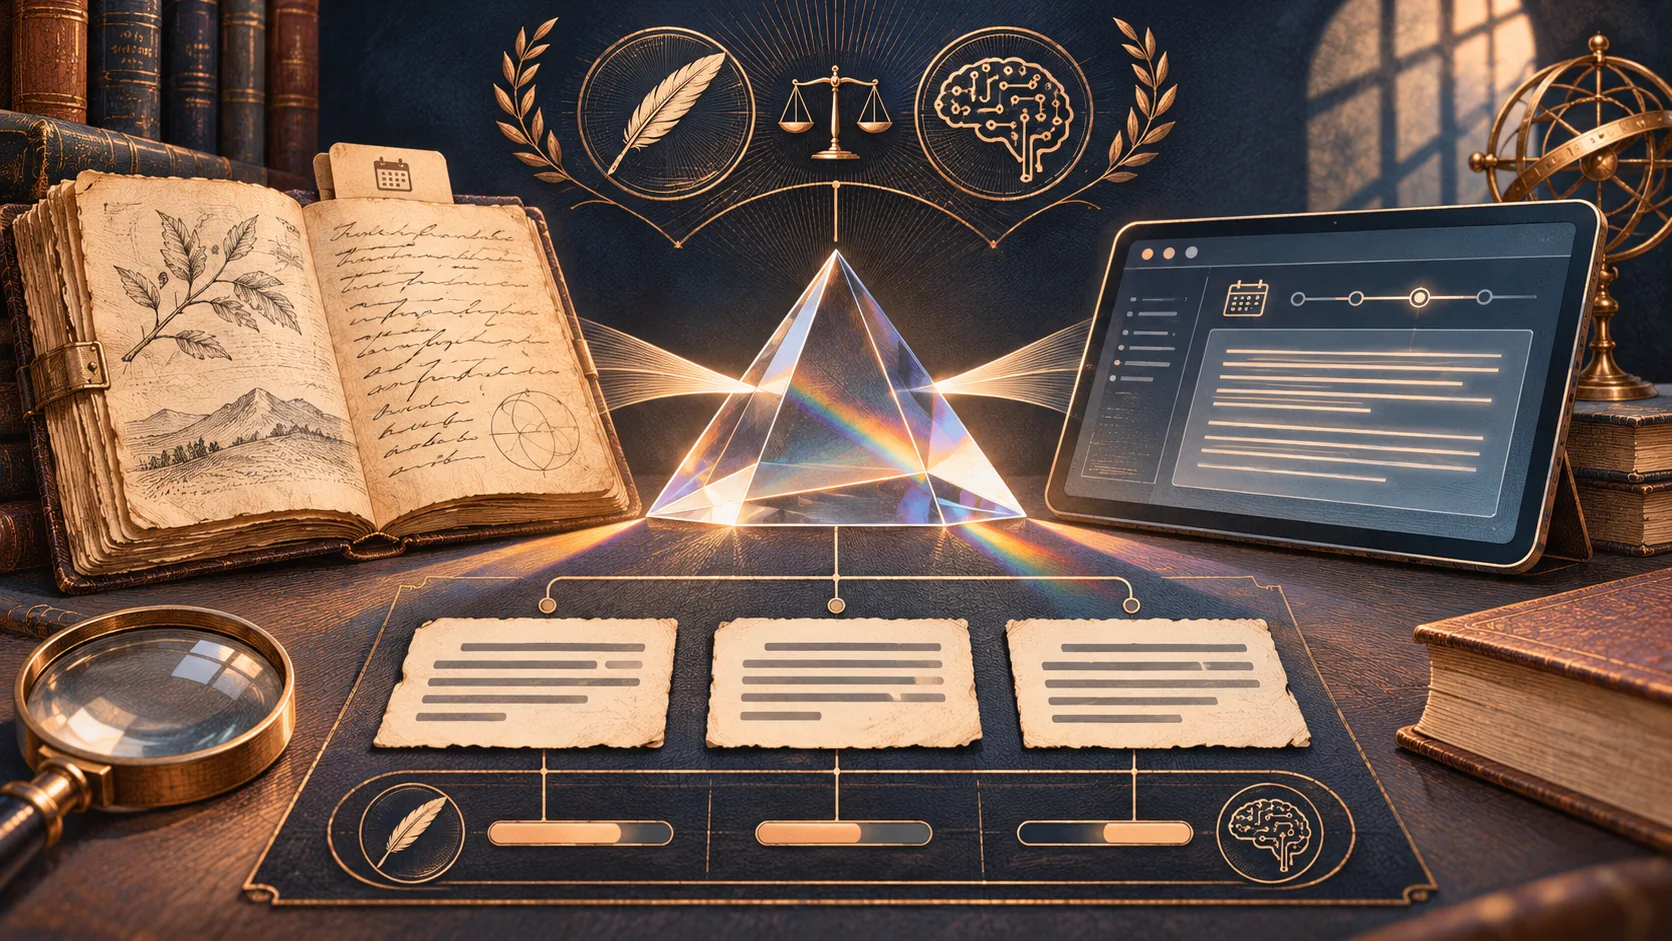
Original draft, image, video, post, or manuscript page. Preserve the file, URL, available metadata, and the date Illa says it was created or published.
Exact public URL or original capture, publication date, account or channel, and the particular phrase, image, or passage that appears to match.
Search query or AI prompt, service and mode, date and time, whether a link or excerpt was supplied, and any cited sources or platform notice.